Korva is a scroll of the internet’s best ideas.

The hidden workspace
Humans have a version of this. Nobody consciously tells their legs to walk through a subway station, because the brain handles that behind the scenes while attention stays on whatever is playing in their ears. Researchers wanted to know which sliver of a model's processing is that kind of hidden work, and the JSpace turned out to be a mental whiteboard where the model's thoughts get processed.
Reading the whiteboard
Reading the whiteboard takes a mathematical translator called a Jacobian lens, which calculates every layer between the inputs and the outputs and puts that math into words. It belongs to mechanistic interpretability, the neuroscience of models. When a model is asked to count 1 2 3 4 5, its whiteboard comes up with words like pathway, a word the answer never contains.
Editing a thought
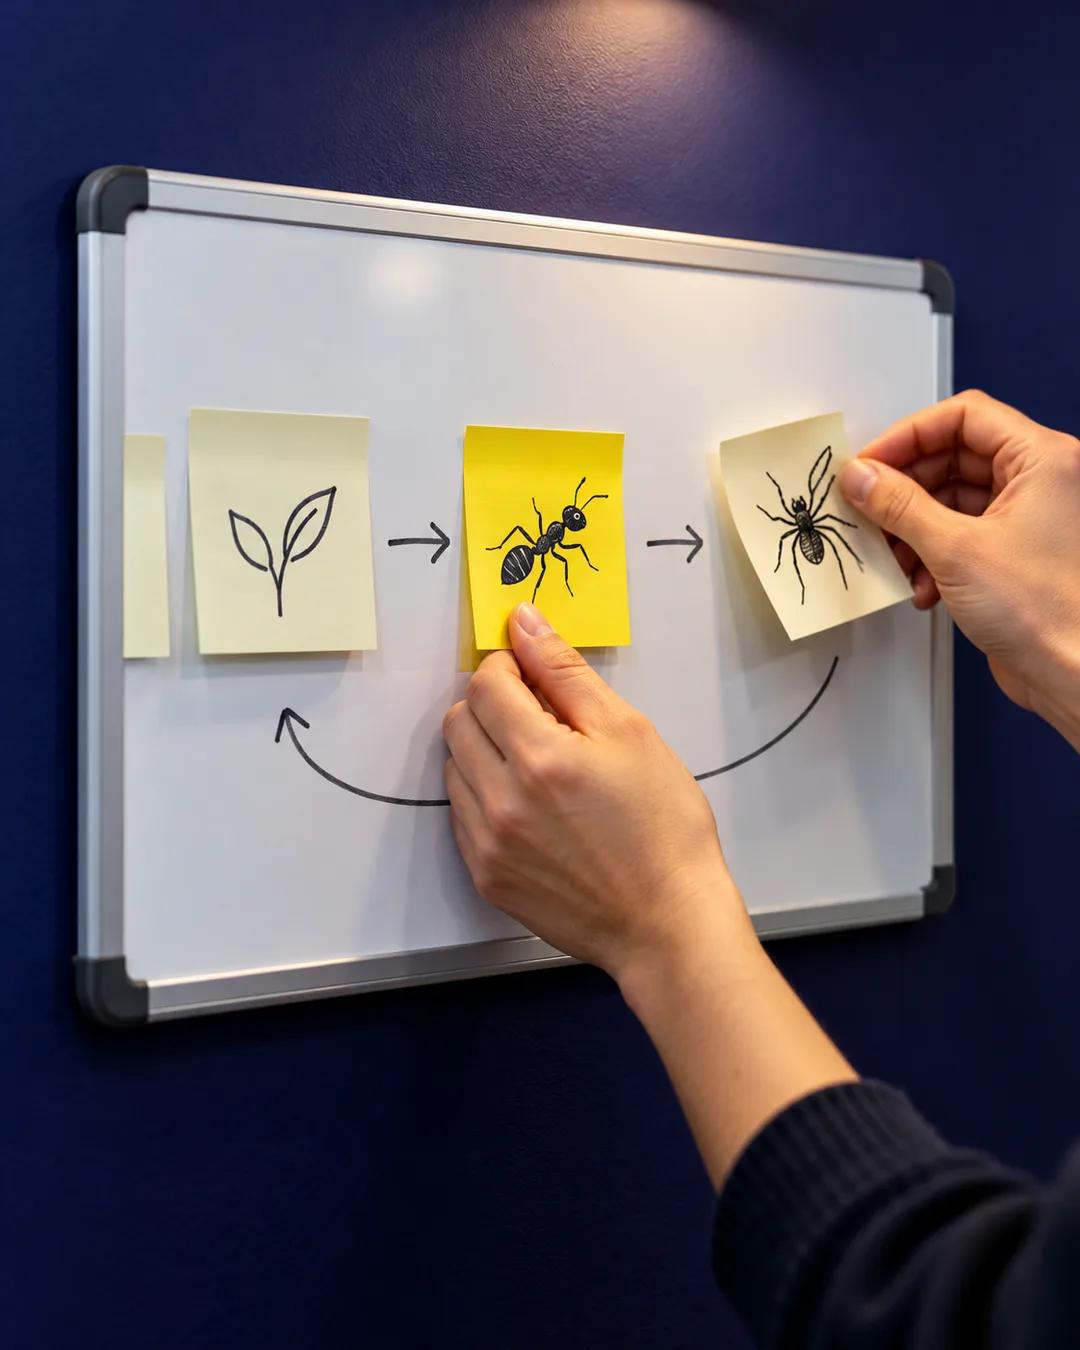
The whiteboard can be edited, too. Asked for the number of legs on the animal that spins webs, a model first has to land on spider and then work out the legs. A researcher swapped spider for ant on the whiteboard and changed nothing else about the model, and the answer followed the swap, like trading one sticky note for another.
How can swapping a thought change an answer?
Anthropic's 2025 interpretability research on Claude traced multi-step questions through the model's internal features. When asked for the capital of the state containing Dallas, the model first activated a concept for Texas and then one for Austin. Researchers swapped the Texas concept for California, and the model answered Sacramento instead.
How did earlier tools peek inside model layers?
In 2020, a researcher posting as nostalgebraist described the logit lens, which reads a language model's intermediate layers as if each one were the last. A transformer passes text through dozens of layers, each adding to a running vector, and the logit lens translates that vector into likely next words partway through. It showed that a model's guesses sharpen gradually from layer to layer. A 2023 paper introduced the tuned lens, which corrected distortions in the plain version.
Why would a model hold thoughts it never says?
A language model writes one word at a time, but each word comes out of a computation spread across many layers. Whatever those layers compute that does not become the output word stays internal. Anthropic's 2025 research on Claude found, for example, that when writing rhyming poetry the model picked a rhyme word ahead of time and then wrote the line toward it.
More from Lightspeed Venture Partners