AI Can Write, but It Cannot Predict a Falling Sippy Cup
Teaching AI to understand cause and effect will mean training it on video of real life, which Cuban says takes a magnitude more tokens, the chunks AI processes, than text.
 All-In with Chamath, Jason, Sacks & Friedberg · Mark Cuban on the AI Bubble: Who Actually Gets Wiped Out?
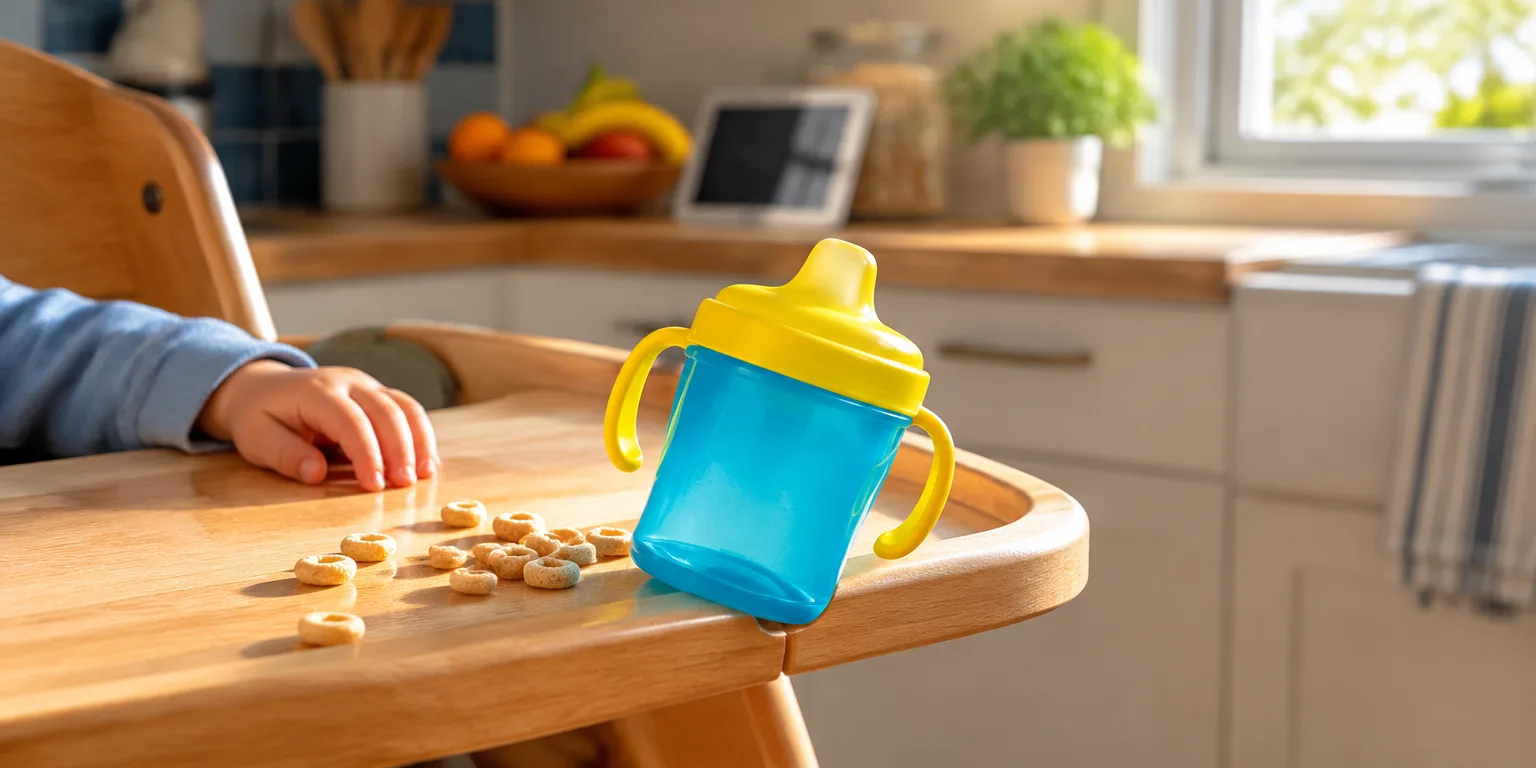
Show today's smartest AI system footage of a toddler in a high chair nudging a sippy cup toward the edge, and it has no idea what happens next.
A toddler knows. The cup will fall, mom will come running, and the kid will laugh. The AI, built to predict words and describe pictures, does not know that chain of cause and effect because it has never lived it. As investor Mark Cuban puts it, if you stood blindfolded at a street corner, you would rather trust a seeing-eye dog to get you across than a phone running AI.
That gap is the difference between the AI chatbots we use now and what researchers call world models. The AI chatbots we use now learn patterns in text and still images. They are excellent at finishing sentences. They are poor at predicting physical consequences.
A world model tries to learn the way a child does, by watching what happens in the world over time. The idea is that with enough video, it can start to learn what happens after a cup tips off a high chair.
Cuban, who invested in a company called Matter.com, describes it as launching satellites to take video of what is below them. He says the company uses spectrography to turn that video into a world model in a way he does not fully understand, to provide algorithms other world models can use.
He says video will have to be part of AI's future.
When the discussion turned to the bet on building out giant data centers, Cuban says, "if I'm going to be wrong on the data centers, it's going to be because of video," noting that world building and video take what he calls "a magnitude more tokens" and that world models and robotics are all related.
For now, the dog still wins.
Questions people ask
What exactly is a world model?
It is an AI system that tries to learn how the physical world behaves, so it can predict what will happen next if something moves or changes. Instead of mainly reading text, it trains on video and sensor data where objects fall, collide, spill, or get picked up. The goal is a kind of common sense about physics and people.
Why does video need so much more computing power than text?
Text is compact: a whole page becomes a few thousand tokens, the chunks AI processes. Video is a rapid stream of high-resolution images, so even a short clip can contain millions of tokens. Training and running models on that flood of detail requires more storage, faster chips, and larger data centers.
Are world models already being used?
Yes, in limited ways. Self-driving car companies use video prediction to anticipate pedestrians and other cars, and robotics labs use similar models to practice grasping and walking in simulation. What does not yet exist is a general, reliable model that understands everyday scenes as well as a toddler does.