AI step-by-step text may be mumbling that jogs memory
The step by step text looks like logic, but experiments show even wrong or irrelevant steps can still lead to right answers.
 Quanta Magazine · Is AI Reasoning Right for the Wrong Reasons?
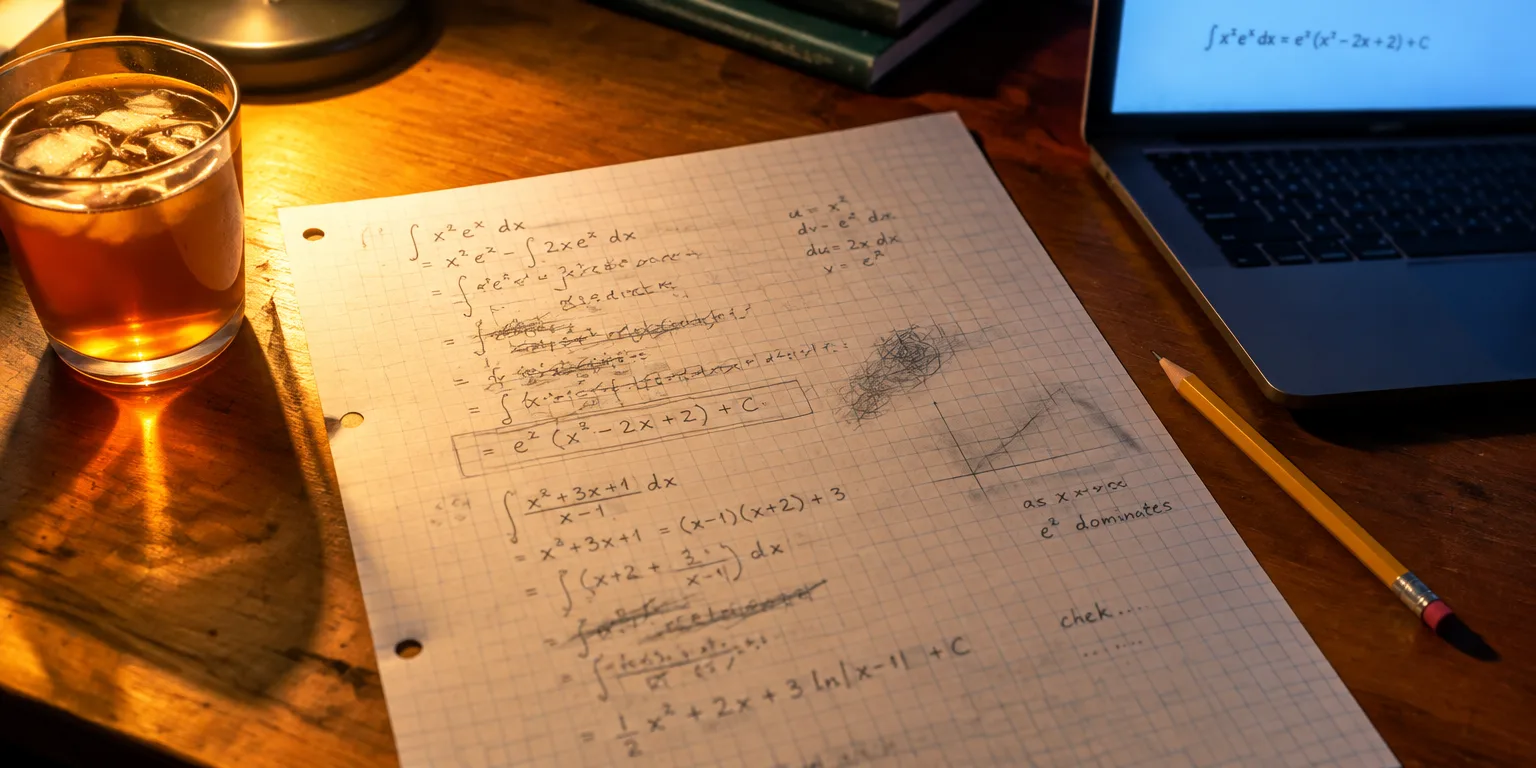
When an artificial intelligence model solves a hard math problem, it shows its work. It writes out steps, pauses, says aha, and then gives the answer. It looks like thinking.
It may be something stranger and more familiar: mumbling to jog a memory.
That is the working hypothesis of Subbarao Kambhampati, an artificial intelligence researcher at Arizona State University. He hardly considers his case closed, but he argues the step by step text is likely not a record of reasoning. The newest systems, called large reasoning models, starting with OpenAI's o1 in 2024, are trained to generate their own step by step prompts, dubbed thinking traces that get looped back into themselves as input. The extra text creates what looks like a paper trail of thought.
In his working hypothesis, the model is likely doing what he calls approximate retrieval. A large language model has absorbed vast numbers of examples of written reasoning, from textbooks, code, proofs, and forums, stored not as facts but as numerical patterns that capture how similar one passage is to another. The thinking tokens fill its short term memory, called a context window, so it becomes likelier to guess the next plausible, reasoning shaped string. Like a person muttering half remembered words while trying to recall a name, what matters is that the muttering knocks something loose.
That would explain an otherwise baffling result. In 2025, Kambhampati's lab swapped out accurate step text for faulty or unrelated text on a formal reasoning task, and performance did not degrade. Even training on only correct traces still occasionally led the model to produce flawed accounts of how it got there, even when the final answer was right.
It also fits where these models shine. In coding and math, what researchers call verifiable domains, code either runs or it does not, and a proof is either correct or not. Those clear yes or no signals, plus written examples of intermediate steps, give the model plenty to imitate. It does not need to learn a general rule of logic, Kambhampati argues, only enough examples to assemble a believable answer that can later be checked.
So the words can be English, or bits of other languages, or fake aha exclamations, or even dots. Whether they map neatly to a word, much less to a faithful process, is beside the point, in his view. The limit is how far that imitation can stretch, a boundary called the inference horizon that Apple researchers probed in a 2025 critique called The Illusion of Thinking. More recent models seem to have extended that boundary, though unevenly. In Kambhampati's view, most of the time they are probably still not learning the algorithm, just leveraging more examples and clever rewards.
Questions people ask
What is a context window?
A context window is the amount of text a model can consider at once when it predicts what comes next. Thinking tokens fill that window with related patterns, which steers the next prediction. It is less like writing in a notebook and more like priming a search.
Can AI really reason with dots?
A 2024 paper from researchers at New York University found that meaningless filler tokens, literally strings of dots, could function effectively in place of a human-readable chain of thought. On Kambhampati's argument, that fits because the tokens prime recall rather than narrate logic.
Why are math and coding special for AI?
They are tasks where success is easy to check automatically. Software either runs or crashes, and math proofs can be verified. That binary feedback is ideal for training, because the model can try many mumbled paths and keep the ones that reach a correct, checkable answer.