The same expert-written training data trains both U.S. and Chinese AI
U.S. PhDs write and double-check the science and coding answers because chatbots have run out of open web data to learn from.
 All-In with Chamath, Jason, Sacks & Friedberg · Google’s AI Brain Drain, SpaceX's Huge Quarter, Airtable’s 90% Collapse, US Data Fuels China AI
The same lessons that make American chatbots smarter are also sold to China.
A Forbes investigation reports that U.S. data companies including Surge AI and Mercor sell training datasets to OpenAI, Anthropic, and federal agencies, and sell the same datasets to leading Chinese labs including Tencent, ByteDance, Alibaba, and Moonshot. The report puts spending by China's top six labs at $500 million a year.
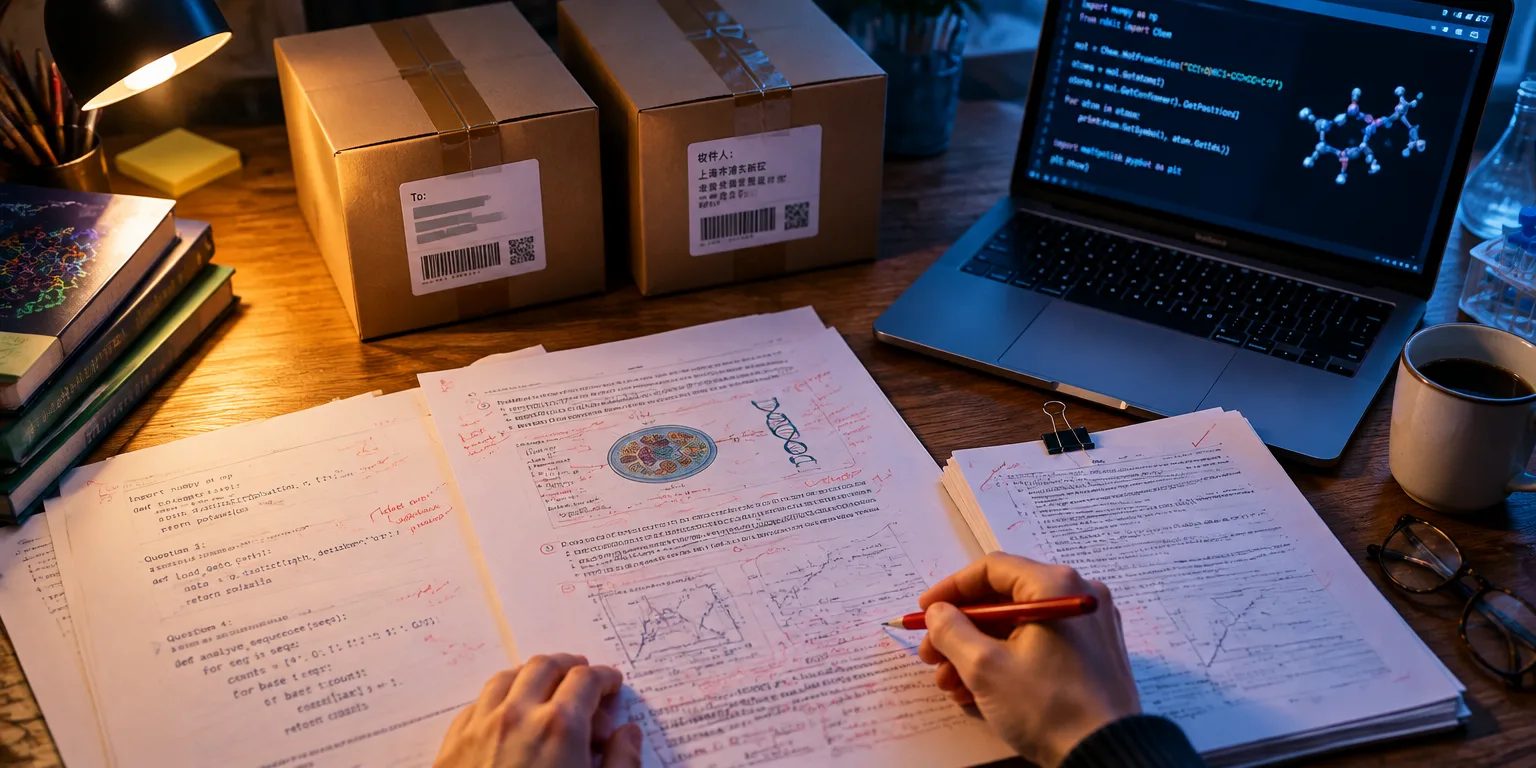
The reason is that chatbots have run out of open material on the web to learn from, so builders now have to manufacture new lessons. That work starts when a model gives a wrong or weak answer to a highly technical question in code, biology, or science.
An American PhD in that field then steps in. The expert writes the correct answer, adds the latest knowledge, and verifies it. Another expert checks it again. Tech investor Jason Calacanis said this double verification is a major reason large language models keep getting better results.
The data companies bundle those corrected questions and answers into packages. The packages are used for reinforcement learning, a standard method for training models.
Calacanis argued that reselling those same packages lets Chinese labs catch up just as quickly because they get the finished packages instead of having to hire Western experts at scale.
David Sacks, an investor who worked on tech policy in the administration, countered that the material is largely a commodity. He argued that China could produce it on its own because "they're graduating more math and science graduates every year than the rest of the world combined," and has no shortage of labor for the work.
So the two sides disagree on one question: whether these answers contain a truly proprietary secret sauce that China could not easily copy on its own.
Questions people ask
Does buying the dataset instantly make a Chinese model as good as an American one?
No. The data provides examples of correct reasoning in hard subjects, plus scores for right and wrong answers. The model still has to train on computers to absorb those lessons.
How is this different from old-fashioned data labeling?
Ordinary labeling means drawing boxes around cars or marking photos of cats, work that needs little training. This newer work is expert authoring and checking, often by people with doctorates in coding, biology, or other sciences.
Do American labs also have to buy this data?
Yes, American labs buy large amounts of the same kind of expert data. The issue raised in the discussion is not that only China uses it, but that both sides train on identical question sets.