To guess the next word, AI had to learn how the world works
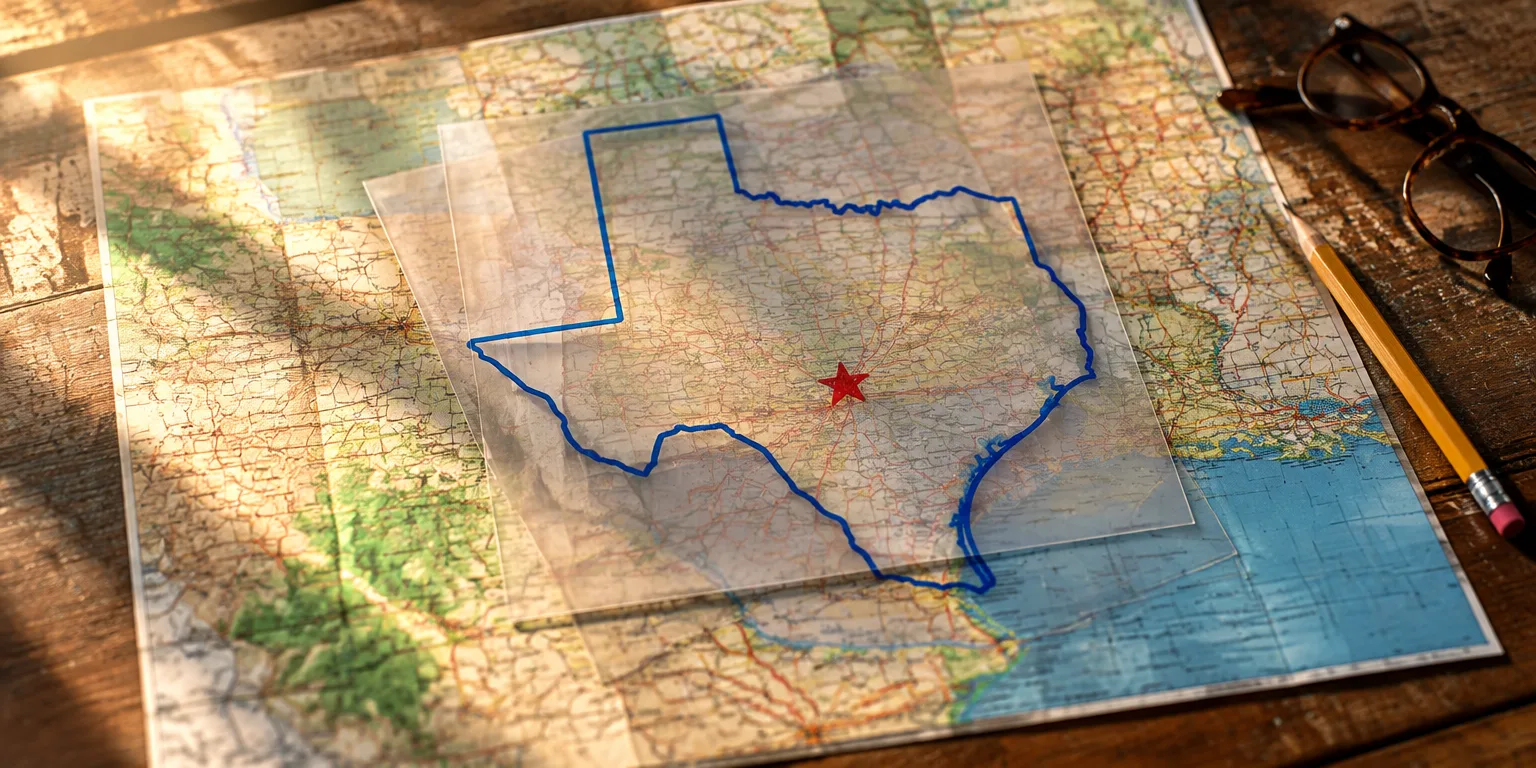
Inside the math, researchers found separate ideas for Texas and capitals that combine to produce Austin.
 Lenny's Podcast: Product | Career | Growth · Inside the black box of AI: How AI models actually think | Emmanuel Ameisen (Anthropic)
Most people picture artificial intelligence as a souped-up version of phone autocomplete. Emmanuel Ameisen, who leads a team studying the insides of AI models at Anthropic, says that mental model is wrong. He describes phone autocomplete as right about 60% of the time and, in his words, "funny and weird the rest of the time," and says people wrongly treat it as the model for AI.
In training, a model reads enormous amounts of human writing and tries, over and over, to guess the next word. Models became better at that guessing game than people around 2019. At first the guesses are easy, just sentence structure. Then the easy words run out.
After that, the only way to keep improving is to get the hard words right, the capital of France in a simple sentence, and eventually the answer to a physics problem or the closing paragraph of a doctoral thesis. Predicting those hardest words is extremely hard, and it is a sort of mystery how a model manages to do it.
To use Emmanuel Ameisen's examples, ask a model to finish the sentence, "the capital of the state that contains Dallas is," and it will answer Austin. A person would solve that by thinking "Dallas is in Texas. States have capitals. The capital of Texas is Austin." Ameisen said that when his team decodes the intermediate steps, the long lists of numbers produced between words, they see the model doing something similar.
In some cases, one pattern of numbers lights up for Texas, another lights up for capitals, and the two combine to trigger Austin. The evidence suggests the model did not just memorize a list of questions and answers. It built reusable ideas and combined them.
The same is true for ordinary objects. Whether the input is a photo of an eye, a medical diagram, a simple computer drawing, or the word for eye in another language, the same internal pattern lights up. It is the model's general idea of eye.
Because models learn by predicting so much text written by people, Ameisen argues that the best way for the model to keep predicting well is to "understand the underlying structure of the world" that produced the text, and he says internal evidence supports that models do this.
Questions people ask
How can researchers actually see an idea like Texas inside a bunch of numbers?
They feed huge amounts of text through the model and record the intermediate numbers at each step. Then they look for patterns that fire only in certain cases, for example whenever Texas is relevant, much like a brain scan shows which areas light up for faces or places. Once they label those patterns, they can test them by tweaking one pattern and seeing if the answer changes as expected.
Could the model have just memorized that Dallas means Austin?
Memorization alone would not explain what the team sees. The Texas pattern and the capitals pattern appear separately and combine to produce Austin, and the team has found such reusable concepts for basically everything, or at least the vast majority of the ones they have tried. That reuse across different questions and contexts is what suggests a general map rather than a memorized list.
Does a bigger, better predictor have a better map of the world?
Generally yes. As models improve at next-word prediction, they move from easy sentence structure to basic facts to expert knowledge like code and science. Ameisen's argument is that getting those harder words right pushes a model toward a richer internal map.