When No Line Can Divide Your Data, Add a Dimension
A simple height trick can turn an impossible sorting problem into one a flat plane can solve, until the math gets too heavy to run.
 Computerphile · Quantum Machine Learning - Computerphile
Imagine a flat page scattered with red dots and blue dots, and your job is to teach a computer to tell them apart. The classic approach, called a support vector machine, is to draw a line between the colors.
Not just any line will do. Of the many lines you could draw, you pick the one that stays as far as possible from the nearest red and blue dots on either side. That maximum margin line becomes the decision boundary, and any new dot that lands on one side gets labeled red, and on the other side gets labeled blue.
That works beautifully when the data behaves nicely. Often, it does not. The red and blue dots can be mixed together in their original two dimensions in a way that no straight line, however cleverly placed, can separate them.
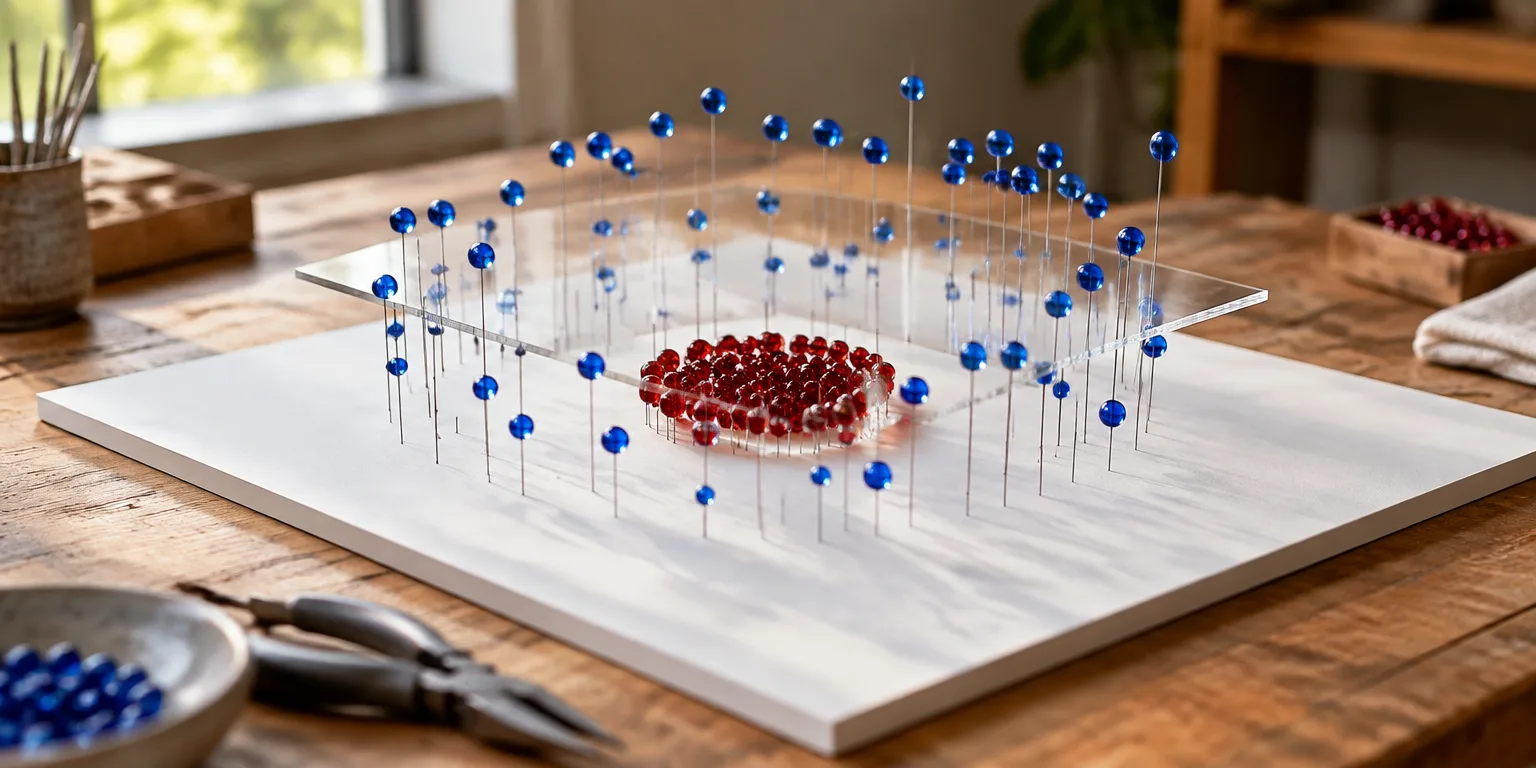
The trick is to stop trying in two dimensions and add a third. Keep each dot's horizontal position, called X, and its vertical position, called Y, exactly the same, but give it a height, called Z, equal to its distance from the center of the page. Dots far from the origin float high, and dots near the origin stay low.
If, for example, the red dots sit near the center and the blue dots sit farther out, the blue dots now hover above the red ones in three-dimensional space. A flat plane, for instance one laid level across the height axis, can slip neatly between the two layers and separate what no line could.
The catch is computation. That separating plane must be calculated in three dimensions instead of two, and real problems usually demand far more than one extra dimension. When the starting data is already complex, lifting it into far roomier mathematical spaces can turn into a bottleneck that does not scale.
Questions people ask
What is a support vector machine actually used for?
A support vector machine is a classification algorithm, a method for sorting new cases into categories learned from old, labeled examples. It is used for tasks like spam filtering, image recognition, and medical diagnosis, where each case can be plotted as a point and the goal is to draw the best boundary between groups.
What does Euclidean distance mean?
It is just the straight line distance between two points, the kind you would measure with a ruler. In two dimensions, it is calculated from the X and Y coordinates using the Pythagorean theorem, so a dot at X equals 3 and Y equals 4 is 5 units from the origin.
Why maximize the distance instead of drawing any dividing line?
The widest margin is the most cautious choice, because it leaves the largest buffer against noise and new dots that fall close to the edge. A line that just grazes one group may fit the old data perfectly but mislabel the next dot that arrives slightly shifted.