Korva is a scroll of the internet’s best ideas.
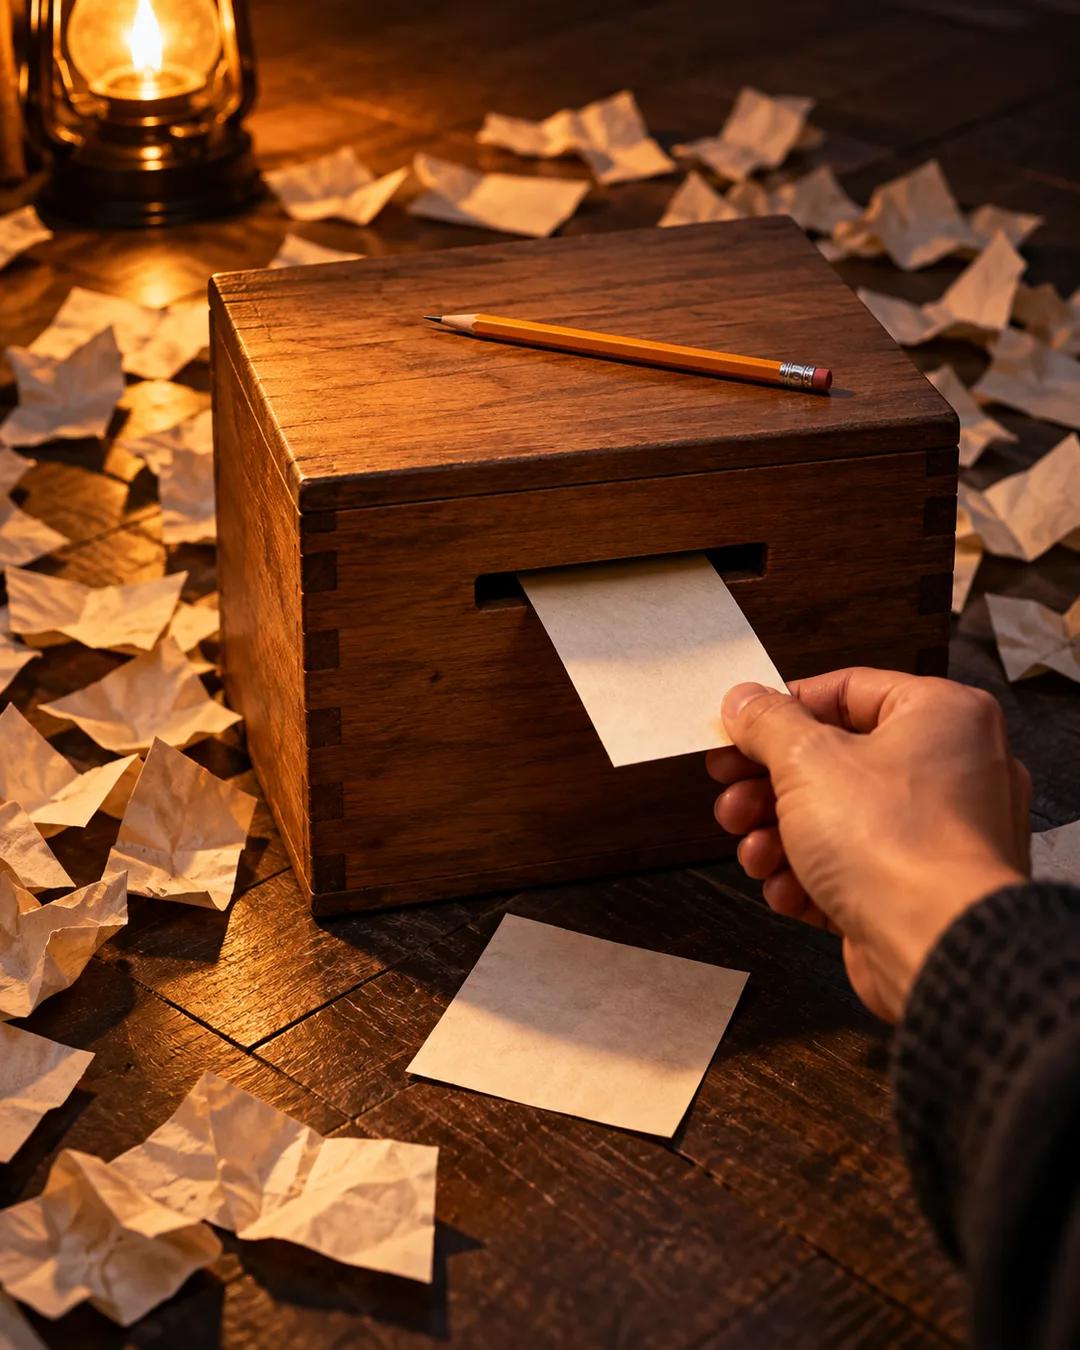
Writing one slip of paper at a time
You predict what comes next, your memory is wiped, and another slip arrives. That repeats a whole bunch of times. Then someone shows you the essay that came out the other end, and you might say it is awful and not the essay you would have written. Repeatedly predicting is very different from the way a writer composes and thinks a piece through.
Under those conditions you would probably be a slave to your context. If you are answering a question about one field, you draw on everything around it. The connection that carries all the substance is, by its nature, a very unlikely one, and it is rarely the predictable next token. All the reinforcement learning in the world raises the question of what specifically rewards making those unlikely connections.
How does a model choose the next word?
The model turns the text so far into a probability for every token in its vocabulary. A sampling step then picks one, with a setting called temperature controlling how often less likely tokens win. The chosen token is added to the text and the process repeats. Nothing is carried between steps except the text itself.
How does reinforcement learning shape writing?
OpenAI's InstructGPT work in 2022 trained a reward model from human rankings of different answers. The language model was then adjusted to produce text that scores higher under that reward model. This is the method behind much of the polish in chat assistants. The reward comes from judgments of finished answers, not from each individual word.
Has this box idea appeared before?
In 1980, philosopher John Searle described the Chinese Room, in which a person who does not read Chinese follows rule books to answer slips of Chinese text passed through a slot. His point was that producing correct answers does not by itself show understanding. The argument has been debated in philosophy and cognitive science ever since.
More from Dwarkesh Podcast